4.5.1. Fabric Unicast Routing
Unicast routing is a critical aspect of fabric configuration. It determines how packets travel from a source to a single destination across the fabric. The SM computes and programs the forwarding tables in each switch, controlling the path that each flow follows. The unicast routing architecture is defined by two independent dimensions:
Addressing mode
How DLIDs are structured and interpreted by switch forwarding tables:
Linear Addressing: Destinations are addressed through a linear forwarding table, with one entry per LID. This mode is straightforward and well suited to a wide range of fabric sizes.
Routing Mode
How the SM and switch hardware select a path for each flow:
Static Routing: The SM assigns a fixed path for each flow so that all packets in a given flow arrive in order. Ordering is maintained within a flow, but not between different flows.
Adaptive Routing: Switch hardware dynamically redirects eligible traffic away from congested links, using local and neighbor congestion telemetry to improve throughput under load.
Addressing mode and routing mode are configured independently. The addressing mode establishes how destinations are identified, and the routing mode then determines the path selection behavior on top of that addressing foundation.
4.5.1.1. Balancing Routing Requirements
When establishing paths throughout the fabric, the SM balances several competing requirements:
Performance across diverse workloads and applications, by load-balancing flows across the available links.
Resilience against link and component failures, by providing alternate paths.
Deadlock avoidance, by ensuring the forwarding tables introduce no cyclic buffer (credit) dependencies.
Efficient use of finite fabric resources, such as forwarding table capacity.
These requirements often involve trade-offs, because optimizing one factor can affect another. For example, maximizing performance may require additional forwarding table entries, while improving resilience may introduce additional hops that increase latency.
To manage these trade-offs, the SM provides configurable routing options. Administrators can select the routing algorithm and tune its parameters to match their fabric topology and workload characteristics, prioritizing the factors most important to their environment. Understanding these routing considerations helps administrators optimize a deployment for specific application requirements and operational constraints.
4.5.1.1. Addressing Modes
The addressing mode determines how the SM assigns and interprets the LIDs used to route unicast traffic through the fabric. The system administrator selects the desired addressing mode in the SM configuration file: opafm.xml. Based on that selection, the SM calculates and assigns the appropriate LIDs during fabric bring-up.
4.5.1.1.1. Linear Addressing
Linear addressing uses a single flat address space for the fabric. During the SM's discovery phase, the SM assigns a LID to each device in the order in which the devices are discovered. Each Switch then routes packets using a linear forwarding table (LFT), in which the destination LID (DLID) directly indexes the table entry that identifies the egress port.
Because each reachable LID requires one forwarding-table entry, the size of the linear address space is bounded by the forwarding-table capacity of the Switches in the fabric. This capacity sets the upper limit on the number of endpoints that can be addressed in linear mode.
4.5.1.2. Static Routing
Static routing establishes a fixed, deterministic path for each flow of packets between a given source and destination. Because every packet in a flow follows the same path, static routing preserves in-order delivery within a flow. The SM computes these paths once and programs them into the switch forwarding tables during fabric bring-up, and recomputes them when the fabric topology changes.
For each source-destination pair, the SM selects a path based on factors such as hop count and the width and speed of each link along the path. Across all node-to-node paths, the SM statically load-balances the routes assigned to each link, distributing traffic as evenly as the topology allows to maximize available bandwidth and reduce the likelihood of congestion. During this process, the SM also ensures that the resulting paths introduce no cyclic buffer (credit) dependencies, avoiding routing deadlock.
4.5.1.2.1. Static Dispersive Routing
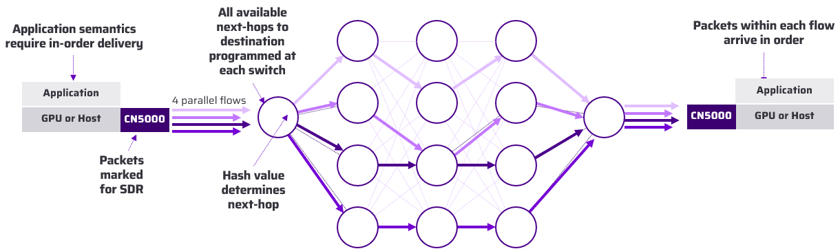
In modern HPC and AI clusters, maximizing bisection bandwidth and eliminating network hotspots is critical. To meet this need, CN5000 uses Static Dispersive Routing (SDR) as its deterministic routing algorithm. SDR spreads traffic as widely as possible across the fabric, enabling deployments to scale to exascale while preserving substantial path diversity. SDR makes routing decisions on a per-flow basis. For each packet, the switch forms a flow ID by hashing a configurable set of packet header fields, which can include:
Destination LID (DLID)
Source LID (SLID)
Layer 4 indication (L4)
Service Channel (SC)
Partition Key (PKey)
Entropy (a dedicated 16-bit field in the 16B header)
Packets that share the same flow ID follow the same physical path to the destination, which preserves in-order delivery within a flow. Packets with different flow IDs are dispersed across the many available physical paths to the same destination. The more variety exposed in the flow ID, the more effectively SDR disperses traffic. The Entropy field is the primary source of this variety: it carries flow-distinguishing information (for example, values derived from the sending application) that is not otherwise available in the packet header.
SDR preserves packet order within a flow because all packets carrying the same Entropy value take the same path. Ordering is not preserved between different flows, which is expected because those flows are intentionally dispersed across different paths. In a fat-tree fabric, SDR can distribute a flow's upward routes across all available links at each tier, driving high load balance and link utilization.
4.5.1.2.2. Routing Algorithms
Routing determines the path that traffic follows between endpoints in the fabric. For every pair of nodes, the SM selects the route used for communication. Route selection typically considers factors such as hop count and the bandwidth characteristics of each link, including link width and link speed, to identify efficient paths through the network.
Beyond selecting individual routes, the SM is also responsible for balancing traffic across the fabric. It statically distributes communication paths across the available links to help prevent congestion and ensure that network resources are utilized efficiently. By spreading traffic over multiple paths, the SM can improve overall fabric performance and avoid overloading specific links.
To accommodate different network sizes, topologies, and workload requirements, the fabric supports multiple routing strategies. These strategies are implemented as selectable routing algorithms, each designed to optimize path selection and load distribution for particular deployment scenarios. Choosing the appropriate routing algorithm can have a significant impact on bandwidth utilization, latency, and overall network performance. The routing algorithm is selectable using the RoutingAlgorithm parameter in the opafm.xml file, and the SM supports the following routing algorithms.
4.5.1.2.2.1. Shortest Path
The Shortest Path algorithm is the default routing method and provides excellent performance for most fabric topologies. It routes traffic along the lowest-cost path between endpoints. In many fabrics, multiple paths have the same cost. When equal-cost paths exist, the SM statically distributes routes across available inter-switch links (ISLs) to balance path utilization.
SpineFirstRouting is an optional enhancement to the Shortest Path algorithm. When enabled, and multiple equal-length paths are available, the SM prefers routing traffic from a DCS leaf through a DCS spine rather than through a Switch located outside the DCS. This approach treats the spine as the "up" direction relative to the leaf, creating a clean and consistent up/down routing model throughout the fabric. By ensuring that traffic follows consistent routing paths, SpineFirstRouting helps prevent credit loops.
For fabrics where Switches are not located at the core of the topology, the Fat Tree routing algorithm can be used to achieve similar spine-first routing behavior. SpineFirstRouting is enabled by default and does not introduce any known adverse side effects. Unlike simpler routing implementations found in some other plane managers, the SM's Shortest Path algorithm includes advanced routing and traffic-balancing capabilities that deliver high performance across a wide range of fabric topologies.
4.5.1.2.2.2. Device Group Shortest Path
Device Group Shortest Path (dgshortestpath) routing is a form of Min-Hop or Shortest Path (shortestpath) routing, except you can control the order in which routes to end nodes are assigned. This can be used to ensure diversity of routing within groups of devices as well as the entire fabric overall. End nodes that are not members of any listed groups will be routed last. When the routing algorithm is set to dgshortestpath, the following section in the opafm.xml file is used to configure the algorithm.
<DGShortestPathTopology>
<!-- RoutingOrder lists the device groups in the order they should -->
<!-- be handled. Each device group must have been declared in the -->
<!-- DeviceGroups section. -->
<!-- <RoutingOrder> -->
<!-- <DeviceGroup>Compute</DeviceGroup> -->
<!-- <DeviceGroup>All</DeviceGroup> -->
<!-- <DeviceGroup>Storage</DeviceGroup> -->
<!-- </RoutingOrder> --></DGShortestPathTopology>
4.5.1.2.2.3. Fat Tree
The Fat Tree routing algorithm typically provides better ISL traffic balancing in Fat-Tree topologies than the Shortest Path algorithm. It also implements an up/down routing model that helps prevent deadlocks. To optimize traffic distribution, the Fabric Manager analyzes the fabric topology, identifies the Fat-Tree structure, and determines the appropriate up/down routing paths based on the tier in which each switch resides.
To identify switch tiers, the Fabric Manager must know the number of switch-chip tiers in the fabric. When all SuperNICs and Target Fabric Interfaces (TFIs) are connected at the same tier, the Fabric Manager can automatically discover the Fat-Tree topology. In environments where endpoints are connected across multiple tiers, you can define a CoreSwitches device group to explicitly identify the root or core Switches of the topology.
When using a CoreSwitches device group, only devices that do not communicate directly with one another should be connected to the core Switches. If devices attached to the core switches exchange traffic, they can potentially create a credit loop.
Credit Loop Avoidance
Because Omni-Path Architecture uses credit-based link-layer flow control, routing paths must be carefully selected to avoid cyclic dependencies between switch output queues and link credits. A credit loop occurs when a set of routes creates a circular dependency in which each packet is waiting for credits that cannot be returned because another packet in the cycle is also blocked. Under sustained congestion or heavy traffic conditions, a credit loop can escalate into a fabric deadlock. When this occurs, recovery mechanisms may be forced to discard packets, potentially resulting in significant performance degradation and reduced fabric stability.
Note
This discussion applies only to the CN5000 Omni-Path Fabric. In CN5000 systems, each Omni-Path plane should be evaluated independently for routing behavior and credit-loop avoidance. Ethernet operation is outside the scope of Omni-Path Omni-SM routing and credit-loop analysis.
Avoiding credit loops is a primary design objective of the routing algorithms used by the SM. For supported topologies, the SM computes routes that maintain an acyclic channel dependency graph, eliminating the circular credit dependencies that can lead to deadlocks. By ensuring that channel dependencies remain loop-free, the SM helps maintain reliable packet forwarding and predictable fabric performance, even under demanding traffic conditions.
One common credit-loop avoidance method is up/down routing, used in Tree and Fat-Tree topologies. In an up/down routing model:
Traffic may move up the topology toward the fabric core.
After traffic begins moving down toward the destination, it must not move upward again.
Routes that would create an up–down–up pattern are avoided because they can introduce cyclic dependencies.
This routing discipline helps ensure that packet dependencies flow in one logical direction through the topology and do not form loops.
When the fabric backbone includes DCSs, the shortest-path algorithm can use spine-first routing to preserve clean up/down behavior across the DCS structure. This behavior is enabled with the SpineFirstRouting option in the SM configuration.
When SpineFirstRouting is enabled, and multiple equal-length paths are available, the SM prefers paths that route traffic from a DCS leaf through the DCS spine rather than through an external edge path. This treats DCS spine as the “up” direction relative to the DCS leaf, helping maintain consistent up/down routing across the fabric.
For CN5000 deployments with multiple Omni-Path planes, each plane should use a topology and routing configuration that independently preserves credit-loop-free routing.
The Fat Tree routing algorithm also avoids credit loops in fabrics where the backbone is not composed of DCSs. In a Fat Tree, traffic is routed upward toward the core only as far as needed, then downward toward the destination. The algorithm applies spine-first behavior throughout the fabric core, ensuring routes follow the expected up/down progression through the topology.
This prevents routes from crossing between tiers in a way that could create cyclic credit dependencies.
If a credit loop is suspected, or after making topology or routing configuration changes, validate the fabric with: opareport -o validatecreditloop. Run this validation for the relevant Omni-Path or plane. Investigate and correct any reported credit-loop risks before placing the fabric under production load.
4.5.1.3. Adaptive Routing
A limitation of static routing is that it must be done before traffic begins to flow. Static routes are balanced using best guesses by the Fabric Manager and sysadmin of potential application traffic patterns. However, once applications start to run, those routes may not be ideal. Adaptive routing allows the switches to adjust their routes while the applications are running to balance the routes based on actual traffic patterns.
The Cornelis adaptive routing solution is highly scalable because it allows the Fabric Manager to provide the topology awareness and program the switches with the rules for adaptive routing. Thereafter, switches can dynamically and rapidly adjust the routes based on actual traffic patterns.
This approach ensures a scalable solution because as switches are added, each new switch works in parallel with others to dynamically adapt to traffic. Additionally, this approach removes the Fabric Manager as a bottleneck.
Adaptive routing provides a few important capabilities and options:
Adaptive routing can rapidly route around fabric disruptions and lost ISLs.
When adaptive routing is enabled, this capability automatically occurs and limits the amount of lag time between an ISL going down and the traffic being redirected to alternate routes.
Adaptive routing can automatically balance and re-balance the fabric routes based on traffic patterns.
Adaptive routing has the ability to handle changing traffic patterns that may occur due to different computational phases or the impacts of starting or completing multiple applications that are running on the same fabric.
4.5.1.3.1. Fine Grained Adaptive Routing
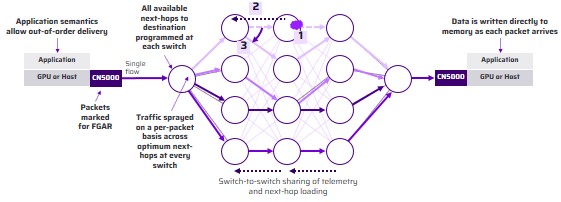
When Fine Grained Adaptive Routing (FGAR) is enabled, the SM programs each switch with a list of alternate, equal-cost routes for each destination in the fabric. When a Switch detects that a route is congested (due to congestion or a complete link or switch failure), it selects an alternate from the list of alternates and updates its linear forwarding table (LFT) with the selected route.
Note
For linear Fat Tree, when FGAR is enabled, so is SDR. When FGAR is disabled, neither FGAR nor SDR is enabled.
The following is the AdaptiveRouting section of the opafm.xml file configured for FGAR:
        <!-- Configures support for AdaptiveRouting in Cornelis Switches -->
    <!-- Adaptive Routing monitors the performance of the possible paths between -->
<!-- fabric endpoints and periodically rebalances the routes to reduce -->
    <!-- congestion and achieve a more balanced packet load -->
    <AdaptiveRouting>       <!-- 1 =
Enable, 0 = Disable -->
      <Enable>0</Enable>
      <!-- When set, Fine Grained routing algorithm will be used to route packets -->
      <!-- If set using fat tree, LMC will be replaced by SDR ignoring LMC tags -->
      <FineGrained>0</FineGrained>
      <!-- When set, only adjust routes when they are lost. -->
<!-- If not set, adjust routes when they are lost and -->
      <!-- when congestion is indicated. -->
      <LostRouteOnly>0</LostRouteOnly>
 <!-- Algorithm the switch should use when selecting an egress port -->
      <!-- Algorithms are currently 0 = Random, 1 = Greedy and -->
      <!-- 2 = GreedyRandom. Default is 2. -->
      <Algorithm>2</Algorithm>
      <!-- Update Frequency: Specifies the minimum time between -->
<!-- AR adjustments. Values range from 0 to 7 and are read as 2^n -->
      <!-- times 64 ms. Default is 0. -->
      <ARFrequency>0</ARFrequency>
      <!-- Congestion threshold above which switch uses adaptive routing. -->
<!-- Congestion threshold is per-VL and measured by tag consumption percentage. -->
      <!-- Values range from 0 to 7. -->
      <!-- 7, 6, 5, 4 correspond to 55%, 60%, 65%, and 70%, respectively. -->
<!-- 3, 2, 1 correspond to 80%, 90%, and 100%, respectively. -->
      <!-- 0 means "Use firmware default". Default is 3. -->
      <!-- Higher Percentage means higher congestion is required before Adaptive -->
      <!-- routing takes control. Higher Percentage is less sensitive, less adaptive. -->
      <Threshold>3</Threshold>
    </AdaptiveRouting>$›$
Note
To enable FGAR, both the AdaptiveRouting and FineGrained settings must be enabled.